The problem that starts on day one
Smart TVs look simple, but the operating system hides lots of failure points: apps that crash after updates, remote lag, streaming drops, privacy leaks and update bricks. Owners notice these problems immediately; manufacturers notice them when returns climb. If you’re responsible for releases, the question is urgent — what tests actually catch the real faults before a product ships? For teams balancing hardware schedules and software complexity, having clear test priorities avoids last-minute panic and wasted cycles, and when hardware comes bundled with software offers you may even compare packages like all in one computer deals to see how integrated ecosystems behave.
Why this is a problem-driven approach
Start from failures you’ve seen. When you drive testing from concrete customer pain points, you stop chasing theoretical edge cases and focus on what breaks deployments, support costs and brand trust. List top field complaints first and design tests to reproduce them reliably. That way your test suites become instruments for prevention, not just late-stage gatekeepers.
Priority test areas that catch the most harm
Functional stability: Automated smoke tests for boot, app launch, input handling and sleep/wake consistency. Network resilience: Simulate flaky Wi‑Fi, captive portals, IPv6 and intermittent DNS failures to ensure graceful recovery. Update resilience: Test interrupted OTA updates and ensure rollback paths are reliable. Performance under load: Run multiple heavy apps and measure memory pressure, frame drops and thermal throttling. Security and privacy: Validate permission boundaries, patching, and secure storage of credentials. Interoperability: Confirm HDMI-CEC, casting protocols, and accessory pairing across common vendor stacks. Each of these areas maps to real customer complaints and to measurable pass/fail criteria.
How to make tests practical and repeatable
Turn reproducible incidents into test cases. Capture logs and full repro steps when a field fault occurs, then script that sequence in CI. Use device farms or emulation for early feedback, and reserve physical hardware for long-duration soak tests and real input device handling. Keep test data small and focused so nightly runs finish quickly; longer soak or update-recovery runs can execute in a separate daily window.
Common pitfalls and how to avoid them
Over-testing rare paths is costly. Under-testing integration is fatal. Don’t trust unit tests alone for behaviour that depends on network or hardware timing. Avoid brittle UI automation: prefer semantic queries over pixel checks. Do real-world network conditioning rather than synthetic up/down toggles. Finally, log provenance matters—store full system traces so you can link a failing test back to firmware, middleware or app version without guesswork.
Experience and real-world grounding
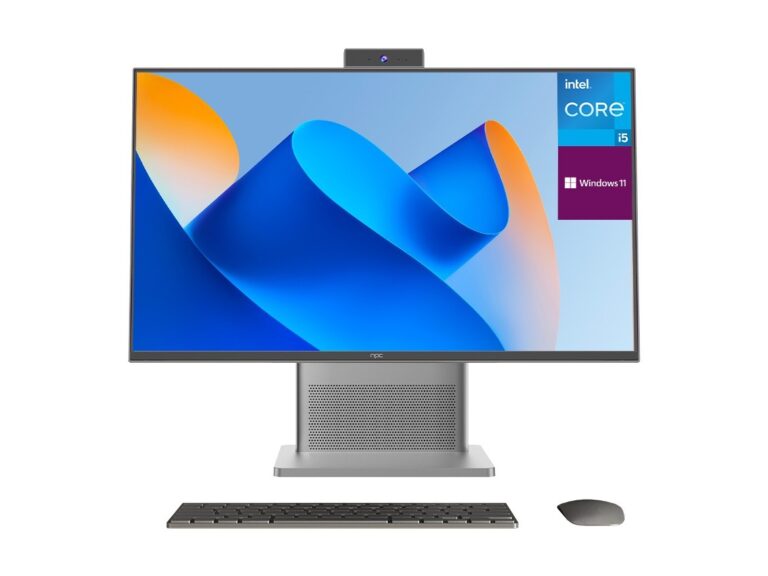
I’ve seen the difference between teams who pass certification and teams who ship good products: the real gap is practice. Major vendors showcased integrated all-in-one designs at CES Las Vegas, and those demos repeatedly highlighted issues around update flows and accessory pairing—problems you can catch with targeted regression tests. That practical perspective is why teams examine market offerings when planning QA; for example, comparing feature bundles with all in one pc deals can reveal common integration choices that influence test priorities.
Alternatives and trade-offs
You can choose heavy automation, lots of manual exploratory cycles, or a hybrid. Full automation scales but misses human-discovered quirks; pure manual testing catches nuance but won’t scale. The sensible path is hybrid: automate regression and network conditioning, allocate regular exploratory sessions for UX flows, and schedule long soak tests on representative hardware builds.
What success looks like
Fewer field returns, quicker triage from user report to root cause, and predictable update rollouts. Define measurable goals: mean time to detect regression, update rollback success rate, and crash-free session percentage. Tie those to release criteria and watch support costs fall.
Final synthesis
When you begin with concrete problems, pick tests that reproduce those failures and keep cycles short, you create a quality process that shields customers and engineers alike. That approach, combined with practical market awareness, is the kind of advice development teams appreciate when they evaluate partners like npc.